
Evidence rating
Effect score (E): 5/5 Evidence for the underlying principle or measurement method.
Transfer score (T): 5/5 Evidence for reliable results in digital product practice.
Evidence level: High
[Supported by practice tests] Predefine the hypothesis, primary metric, sample/duration plan, and guardrail metrics before an experiment.
Scale and rating rules
Effect score: 5 established · 4 robust · 3 context-dependent · 2 weak · 1 preliminary.
Transfer score: 5 practice-proven · 4 field-supported · 3 partially supported · 2 plausible · 1 hypothesis.
Without a robust scientific or normative source, E is capped at 3. Blog and agency opinions support at most T=2. If evidence conflicts, the more conservative score applies until justified otherwise.
Evidence level: High = E ≥ 4 and T ≥ 3; Moderate = E ≥ 3; Preliminary = E ≤ 2 or T ≤ 1.
A/B tests & Multivariate Tests
A/B tests and multivariate tests are among the most important quantitative methods in UX research and conversion optimization. They make it possible to find out, based on data, which variant of a user interface works better for real users - whether in terms of click behavior, completion rates or dwell time. These methods are particularly widespread in the digital product environment, as they are fast, scalable and relatively easy to implement.
What is an A/B Test?
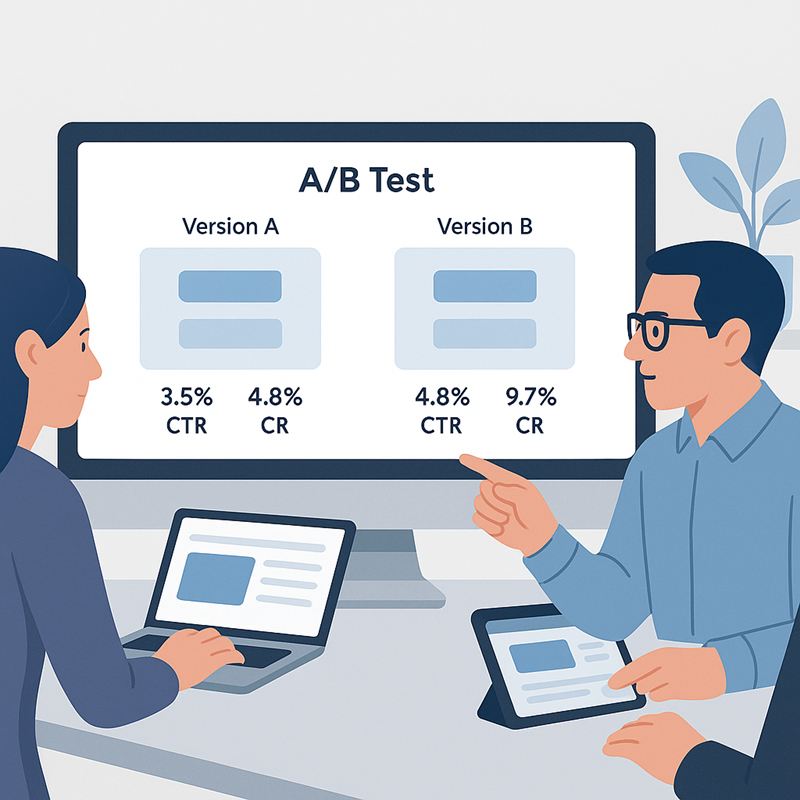
In an A/B test, a digital component - such as a call-to-action button - is created in two versions: Version A represents the initial solution, version B contains a targeted change, such as a different color or wording. The variants are then randomly played out to different user groups so that their effect can be measured in a real usage context.
A hypothetical example: An e-commerce store compares two product pages. In version A, the “Add to cart” button is below the product description; in version B, it is higher up. After two weeks, version B has a 12% relative increase in conversion rate. This is initially an observed difference; a sound causal interpretation requires, among other things, randomization, consistent measurement, adequate sample size, and a prespecified analysis.
A/B tests can evaluate copy, processes, and navigation as well as visual elements. If several elements change, the test initially estimates the effect of the variant package; it cannot isolate each element’s contribution. That requires an appropriately planned factorial or multivariate design.
What is a Multivariate Test?
Multivariate tests examine several factors at once, such as button color, headline, and image selection. Depending on the design, combinations are tested in parallel; complexity and sample-size requirements grow as factors are added.
For example, a landing page is tested for button color, headline, and image. An appropriate multivariate design can estimate whether individual factors or their combinations relate to a target metric. Reliable estimates require a suitable design and enough data.
However, as the number of variables tested increases, so do the requirements in terms of traffic - because reliable statements can only be made with a sufficient number of users.
When are such Tests Useful?
A/B and multivariate tests are particularly useful when it comes to iteratively optimizing existing interfaces. They are ideal for answering questions such as: “Does the new button labeling work better?” or “Is the new checkout process canceled less often?”.
The prerequisite is that a certain number of users already exist so that the results are statistically meaningful. Clear success metrics should also be available - such as click rate, conversion, bounce rate or the number of completed forms.
A/B tests are less suitable in very early design phases when there are no functioning interfaces or no clear target definition.
Advantages from a UX Perspective
A key advantage of A/B tests lies in their objectivity: instead of speculating about design issues, they provide empirical data on the actual effectiveness of individual variants. Even small changes can be evaluated quickly - such as changing an icon color or the placement of a label. Such tests are now part of the standard repertoire, especially in agile teams with continuous deployment.
As many tools already offer automatic evaluation and segmentation, results can be analyzed efficiently - including confidence intervals and significance tests.
Challenges and Limitations
As useful as A/B tests are, they also have their weaknesses. On the one hand, they do not provide an explanation for observed effects. For example, if a variant performs worse, it remains unclear whether this is due to the color, the text or the context. It therefore makes sense to combine quantitative tests with qualitative methods such as interviews or observations.
Another problem is that random effects can lead to false conclusions if samples are too small. The so-called “winner’s curse” - the overestimation of positive results - is also a well-known phenomenon. Tests should therefore be well planned, carried out for a sufficiently long time and critically evaluated.
There is also a risk of focusing on short-term gains (such as higher click rates) without considering long-term user retention or UX quality.
Tools in Practice
In practice, numerous tools are used to carry out A/B and multivariate tests. Well-known platforms such as Optimizely, VWO or Adobe Target offer comprehensive options for test design, segmentation and evaluation. For simpler use cases, tools such as UsabilityHub or Google Optimize are sufficient (the latter has since been discontinued). Those who attach particular importance to data protection will find alternatives such as Matomo or Piwik PRO.
The choice of the right tool depends heavily on the objective, technical infrastructure and resources - and should always be checked in terms of data protection law.
Conclusion
A/B and multivariate tests are quantitative experiments that can estimate predefined differences between variants under appropriate conditions. They do not replace qualitative research or evaluation of other UX goals. Whether an experiment is appropriate depends on the research question, risk, traffic, and available measures.
Frequently asked questions (FAQ)
What is an A/B test?
What is a multivariate test?
When are A/B tests useful?
What advantages do A/B tests offer?
What are the challenges?
Which tools are frequently used?
Research on A/B testing in the UX and usability context
This work examines the methodical use of A/B tests to evaluate and optimize the user experience and their integration into digital development processes.
User Experience Evaluation through Automatic A/B Testing
Combines A/B tests with machine learning for automated UX evaluation in the real context of use.
Gardey, J. C., & Garrido, A. (2020). User experience evaluation through automatic A/B testing. In Intelligent User Interfaces. https://doi.org/10.1145/3379336.3381514
Features of A/B Testing of a Delivery App
Compares A/B testing with usability testing and shows their use in app design with a focus on UX optimization.
Khitskova, Y., Asnina, N., Efimova, O. E., & Makovy, K. (2024). Features of A/B testing of a delivery app. IEEE Proceedings. https://doi.org/10.1109/summa64428.2024.10803747
Bridging Quantitative and Qualitative Digital Experience Testing
Introduces an integrated framework that combines A/B testing with qualitative UX methods to analyze user behavior in depth.
Kumar, R. (2023). Bridging quantitative and qualitative digital experience testing. In ACM SIGIR. https://doi.org/10.1145/3539618.3591873
Science corner: evidence data
- Setting
- Controlled online experiments in real digital products
- Replication status
- Replicated / repeatedly studied
- Evidence level
- High (E=5, T=5)
- Key sources (APA)
-
- Kohavi, R., Tang, D., & Xu, Y. (2020). Trustworthy online controlled experiments: A practical guide to A/B testing. Cambridge University Press. https://doi.org/10.1017/9781108653985
- Kohavi, R., Longbotham, R., Sommerfield, D., & Henne, R. M. (2009). Controlled experiments on the web: Survey and practical guide. Data Mining and Knowledge Discovery, 18(1), 140–181. https://doi.org/10.1007/s10618-008-0114-1
- Kohavi, R., Deng, A., Frasca, B., Walker, T., Xu, Y., & Pohlmann, N. (2013). Online controlled experiments at large scale. Proceedings of the 19th ACM SIGKDD International Conference on Knowledge Discovery and Data Mining, 1168–1176. https://doi.org/10.1145/2487575.2488217
- Crook, T., Frasca, B., Kohavi, R., & Longbotham, R. (2009). Seven pitfalls to avoid when running controlled experiments on the web. Proceedings of the 15th ACM SIGKDD International Conference on Knowledge Discovery and Data Mining, 1105–1114. https://doi.org/10.1145/1557019.1557139
- Review date / version
- 2026-11-01 · 1.1
- Next review
- 2027-11-01 (Review cycle: 12 months)
Last modified: 1 November 2026